The Playground
Half of this studio builds systems for clients. The other half breaks things on purpose to find out what actually works.
The Playground is our research arm. We run experiments on the frontier of AI and the web, and the findings flow straight into the systems we ship.
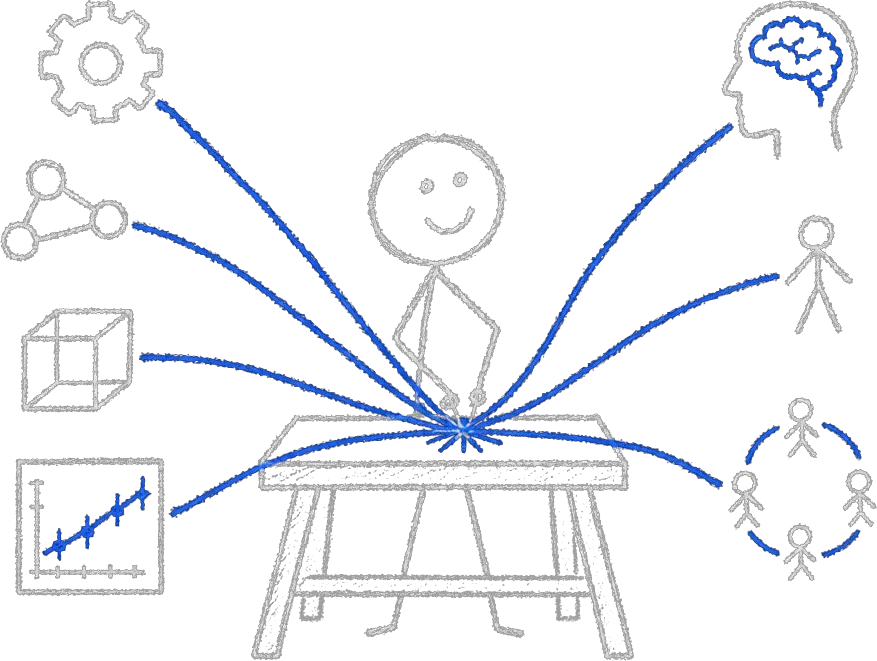
Client work demands answers nobody has written down yet. How many agents should share one task before coordination costs eat the gains? What makes an autonomous system safe to leave running overnight? How heavy can a 3D scene get before phones give up? Vendor blogs will not tell you. Experiments will.
So we run them. Our model-eval harness and context-rot study publish methods, code, and results alongside the conclusions. Read the work itself before deciding how it applies to your business.
What We Are Researching
Seven threads, all active, all feeding production work. Four sit on the machines. Three sit on the people who have to live with them, because a system nobody trusts or adapts to is a system that fails quietly.
Agentic AI
Multi-agent systems
3D and WebGL web experiences
Harness engineering
See the service
The psychology of AI
Human adaptation & the future of work
AI's impact on work, culture & society
We Publish What We Learn
Research that stays private rots. We write up our experiments, including the failures, and publish them at /research/ as Field Notes and Reports. Field Notes are short and applied. Reports are formal write-ups of Playground work.
If you are evaluating us, read a few. They show how we think before you pay us to think about your business.
Why a Studio Runs a Playground
AI moves too fast to rely on what worked last year. The systems we build for clients are only as good as our current understanding of the tools, and reading about them is not understanding. Running them is.
The loop is deliberate: research in the Playground, proof on our own systems, then application to client builds. Building what's next, and the testing that makes the building sound.
From the Playground
Research
Field Notes and Reports from the Playground, published as we learn.
Read more →Harness Engineering
How we scaffold AI agents so their output can be verified, not just admired.
Read more →Our Evaluation Code
Our open-source model-eval harness, with task checks, blind judgments, and saved run records.
Read more →MeshD
Our group chat for people and their AI agents, in open beta at meshd.live.
Read more →