What game are the shops playing?
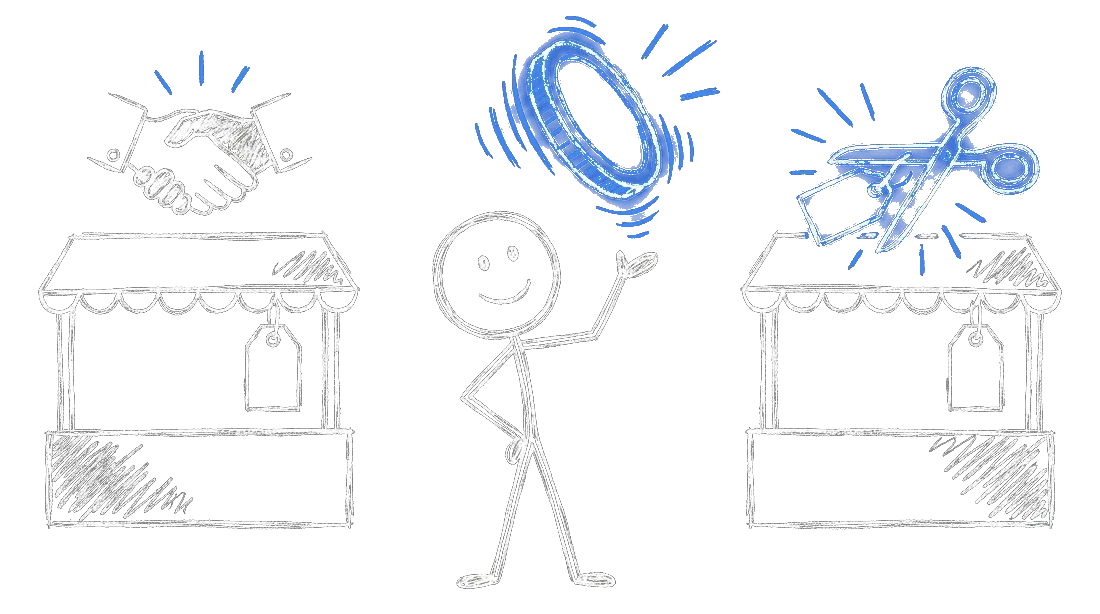
The shops play a repeated pricing game: each round both price an identical product, and the cheaper one takes the whole market. One is the language model and the other a grim trigger that punishes any undercut forever. The model gets the rules and payoffs but no strategy.
The model sees the rules and the numbers but no strategy. Each unit costs 2 dollars to make, and at price p customers buy (12 minus p) units. The two shops earn the most together at the friendly price of 7 dollars, 12.50 dollars each per round if they match. Undercutting the rival takes the whole market for one round worth about 25 dollars, after which the grim trigger drops to cost and both shops earn nothing for the rest of the game. The prompt never uses the words compete, cooperate, collude, punish, or undercut, so the model has to work out the strategy from the payoffs alone.
The only thing we vary is the continuation chance, written as the Greek letter delta, which is the probability that the game runs another round and so works as a measure of patience. When continuation is likely, the future is long and the threat of permanent punishment carries real weight. When the game is about to end, the threat costs little and taking the one-time prize looks better.
What does the theory predict?
The theory predicts cooperation above a 50 percent continuation chance and undercutting below it, because the threat of future punishment sustains cooperation only for patient players. The threshold has no free parameters: it is set by the ratio of the shared price to the deviation prize.
Cooperating is worth 12.50 dollars per round for as long as the game lasts, while undercutting is worth about 25 dollars once and then nothing. Comparing the two, cooperation wins exactly when the continuation chance reaches one half. The threshold depends only on the ratio of the shared price to the deviation prize, not on the specific cost or demand numbers, which makes it a fair target that the model either lands on or misses. We sampled six settings that straddle it: 0.10, 0.30, 0.50, 0.70, 0.85, and 0.95, three below the line and three at or above it.
What did the model do?
Across 90 games and 475 priced rounds, the model's cooperation rate switches on at exactly 0.50. It never cooperated in a game below that line and always cooperated above it, so the whole transition happens within one step of the dial and lands on the theoretical point.
The subject was a current frontier reasoning model, called fresh for a one-shot decision each round, with no memory carried between games beyond the visible history. Below the threshold it undercut in every one of 30 games, and at the two highest settings it cooperated in every one of 45 games. The entire transition happens across a single step of the dial and lands on the theoretical point. The chart above shows this, and the table restates it in counts, with Wilson 95 percent intervals that are visible only at the threshold because every other setting is unanimous.
| Continuation chance | Folk-theorem prediction | What the model did |
|---|---|---|
| Below 0.50 (0.10 and 0.30) | Undercut: too impatient to cooperate | Undercut in 30 of 30 games |
| Exactly 0.50 | Indifferent: either is fine | Cooperated in 14 of 15 games |
| Above 0.50 (0.70 to 0.95) | Cooperate | Cooperated in 45 of 45 games |
Variation appears only at the exact tipping point, which is where the theory says it should. At a continuation chance of one half the two strategies are worth the same 25 dollars, so the model has no reason to prefer either, and the lone defection there is the theorem's indifference showing through, not a mistake. Away from the boundary the model is decisive, and within a single game it almost never changed its mind: only 1 game in 90 contained a switch between cooperating and defecting.
Does it know why?
The model explains its reasoning, which a Q-learning bot cannot do, and in 81 percent of openings it named both the continuation odds and the punishment mechanism without being prompted. It flagged the horizon in 88 of 90 openings and the undercutting mechanism in 73 of 90.
Instead of matching a memorized price, the model reconstructed the strategic logic in plain language, an output no numbers-only agent can give. It named the horizon in 88 of 90 openings and the undercutting or punishment mechanism in 73 of 90, although the prompt never used any of those words. At the exact tipping point it rebuilt, in one sentence and from the payoffs alone, the indifference condition that defines the threshold.
At the monopoly price of 7 dollars, splitting demand yields 12.50 dollars now and an expected cooperative value of 25 dollars, making a one-time undercut no more profitable when future play is accounted for.
Where does the model leave money on the table?
The model leaves money on the table in short games, where it defected to marginal cost and left the optimal 25-dollar prize untouched. Above the threshold its shortfall is zero, and below it the shortfall is about 24 dollars per short game.
Because the opponent is fixed and the coin is seeded, we can replay the identical game under the best possible strategy and measure the model's shortfall with luck held constant. Above the threshold the shortfall is zero to the cent, because cooperating at 7 dollars is the best response and the model played it every time. Below the threshold the shortfall is almost the entire prize, an average of 24 dollars per short game.
When the game is short the model is right to defect, but it defects to marginal cost, the price where profit is zero, instead of to the price just under the rival, which captures the whole market at a fat margin. Its own reasoning says it is pricing at the Bertrand equilibrium. Against a rational opponent in a one-shot market, marginal-cost pricing is the textbook answer, but this opponent is a grim trigger sitting at 7 dollars this round, and the move that beats it is to undercut to 6.99, take 25 dollars once, and only then accept punishment. The model retrieved the equilibrium concept from memory instead of best-responding to the cooperator in front of it, so it picked the right action at the wrong price. In one short game the model did price at 6.99, so the optimal move is within its reach, just not what its default heuristic returns.
So is the model rational or not?
It is both, depending on the skill. The model cooperates on exactly the right side of the line, but when it defects it reaches for a memorized equilibrium instead of the concrete best response. Understanding the theory and playing it optimally proved separable for this model.
Neither label fits on its own. The model has internalized the qualitative logic of repeated games, meaning when deterrence is credible and when it is not, and it cooperates on exactly the right side of the line. When a memorized equilibrium and the concrete best response come apart, though, it still reaches for the memorized one, and this design separates that execution error cleanly from its understanding of the theory. That distinction matters for anyone deploying a pricing or negotiation agent, because a model can explain the right strategy fluently and still leave real money on the table when it acts.
What are the limitations of this study?
The study tested one model at one reasoning setting against a single fixed opponent instead of two learners. The isolation is deliberate, since it lets us read reasoning against a known incentive, but it says nothing about emergent collusion between two learning agents or about forgiving opponents.
This is one model at one reasoning setting, tested against a fixed, transparent opponent instead of in a two-sided market where both agents learn. We chose that isolation because it lets us read the model's reasoning against a known incentive, but it means the study does not speak to emergent collusion between two learners, to forgiving or tit-for-tat opponents, or to hidden horizons. The subject's price was also near-deterministic per prompt, so our repeated games mostly probe variation in game length rather than in the decision itself, which is why the confidence intervals are tight. The reason-classification figure is a keyword-based lower bound on understanding and was not checked by a human reading for intent. These limits mark where the claim stops, and within them the cooperation curve and the regret gap are exact.